

جارٍ تحميل الدرس...
في نافذة الطباعة اختر «حفظ كملف PDF» كوجهة.
تعلم الآلة، الأسبوع 9
صف كل فيلم بكلماته، وقس مدى التشابه بين فيلمين بتشابه جيب التمام، وأوص بالأفلام الأقرب.
CountVectorizer، وبيان وظيفة stop_words وmin_dfcosine_similarity وقراءة صف واحد منهاget_recommendations سطرا بسطر وشرح مواضع خطئهاالأسبوع 9 من الخطة
| الجزء | ما نفعله | الزمن |
|---|---|---|
| 1 | الفكرة، ومثال محلول يدويا | 35 دقيقة |
| 2 | الدفتر: المتجهات ومصفوفة التشابه | 25 دقيقة |
| 3 | get_recommendations ومواضع خطئها | 20 دقيقة |
| 4 | عروض المشاريع والمناقشة | 10 دقائق |
| 5 | تمارين مع الإجابات، ثم الخلاصة | 30 دقيقة |
الجزء 1
محتوى متشابه، ذوق متشابه
texts = ['Action Adventure Fantasy Science Fiction',
         'Adventure Fantasy Action']
cv = CountVectorizer(stop_words='english')
m = cv.fit_transform(texts)
print(cv.get_feature_names_out())
print(m.toarray())['action' 'adventure' 'fantasy' 'fiction' 'science']
[[1 1 1 1 1]
[1 1 1 0 0]]fit المفردات: كل كلمة مختلفة، بحروف صغيرة، ومرتبةtransform كل نص صفا من الأعداد، بعمود لكل كلمةstop_words='english' كلمات التوقف (stop words)، أي الكلمات الشائعة جدا مثل the وofA وB متجها الأعداد لفيلمين، وn عدد كلمات المفرداتa_i وb_i عدد مرات ظهور الكلمة i في كل فيلمA · B هو الضرب النقطي، و‖A‖ هو طول Aيدويا
أول خمسة صفوف من movies.csv، باستخدام العمود genres وحده. أعجب Avatar أحد المشاهدين: أي فيلم نوصي به؟
| الفيلم | genres |
|---|---|
| Avatar | Action Adventure Fantasy Science Fiction |
| Pirates of the Caribbean: At World's End | Adventure Fantasy Action |
| Spectre | Action Adventure Crime |
| The Dark Knight Rises | Action Crime Drama Thriller |
| John Carter | Action Adventure Science Fiction |
['action' 'adventure' 'crime' 'drama' 'fantasy' 'fiction' 'science' 'thriller']الأعمدة بترتيب المفردات
action, adventure, crime, drama, fantasy, fiction, science, thriller
| الفيلم | متجه الأعداد | الكلمات |
|---|---|---|
| Avatar | [1 1 0 0 1 1 1 0] | 5 |
| Pirates of the Caribbean | [1 1 0 0 1 0 0 0] | 3 |
| Spectre | [1 1 1 0 0 0 0 0] | 3 |
| The Dark Knight Rises | [1 0 1 1 0 0 0 1] | 4 |
| John Carter | [1 1 0 0 0 1 1 0] | 4 |
| الفيلم | مجموع المربعات | الطول ‖v‖ |
|---|---|---|
| Avatar | 5 | √5 = 2.2361 |
| Pirates of the Caribbean | 3 | √3 = 1.7321 |
| Spectre | 3 | √3 = 1.7321 |
| The Dark Knight Rises | 4 | √4 = 2.0000 |
| John Carter | 4 | √4 = 2.0000 |
| الفيلم | الكلمات المشتركة | A · B |
|---|---|---|
| Pirates of the Caribbean | action, adventure, fantasy | 3 |
| Spectre | action, adventure | 2 |
| The Dark Knight Rises | action | 1 |
| John Carter | action, adventure, fiction, science | 4 |
A = Avatar، وB = Pirates of the Caribbean
A = Avatar في كل الصفوف
| الفيلم B | الحساب | cos(A, B) |
|---|---|---|
| Spectre | 2 / (2.2361 × 1.7321) = 2 / 3.8730 | 0.5164 |
| The Dark Knight Rises | 1 / (2.2361 × 2) = 1 / 4.4721 | 0.2236 |
| John Carter | 4 / (2.2361 × 2) = 4 / 4.4721 | 0.8944 |
| الترتيب | الفيلم | cos(A, B) |
|---|---|---|
| 1 | John Carter | 0.8944 |
| 2 | Pirates of the Caribbean | 0.7746 |
| 3 | Spectre | 0.5164 |
| 4 | The Dark Knight Rises | 0.2236 |
from sklearn.metrics.pairwise import cosine_similarity

cv = CountVectorizer(stop_words='english')
m = cv.fit_transform(df['genres'].head(5))
sim = cosine_similarity(m)
sim[0]array([1. , 0.77459667, 0.51639778,
0.2236068 , 0.89442719])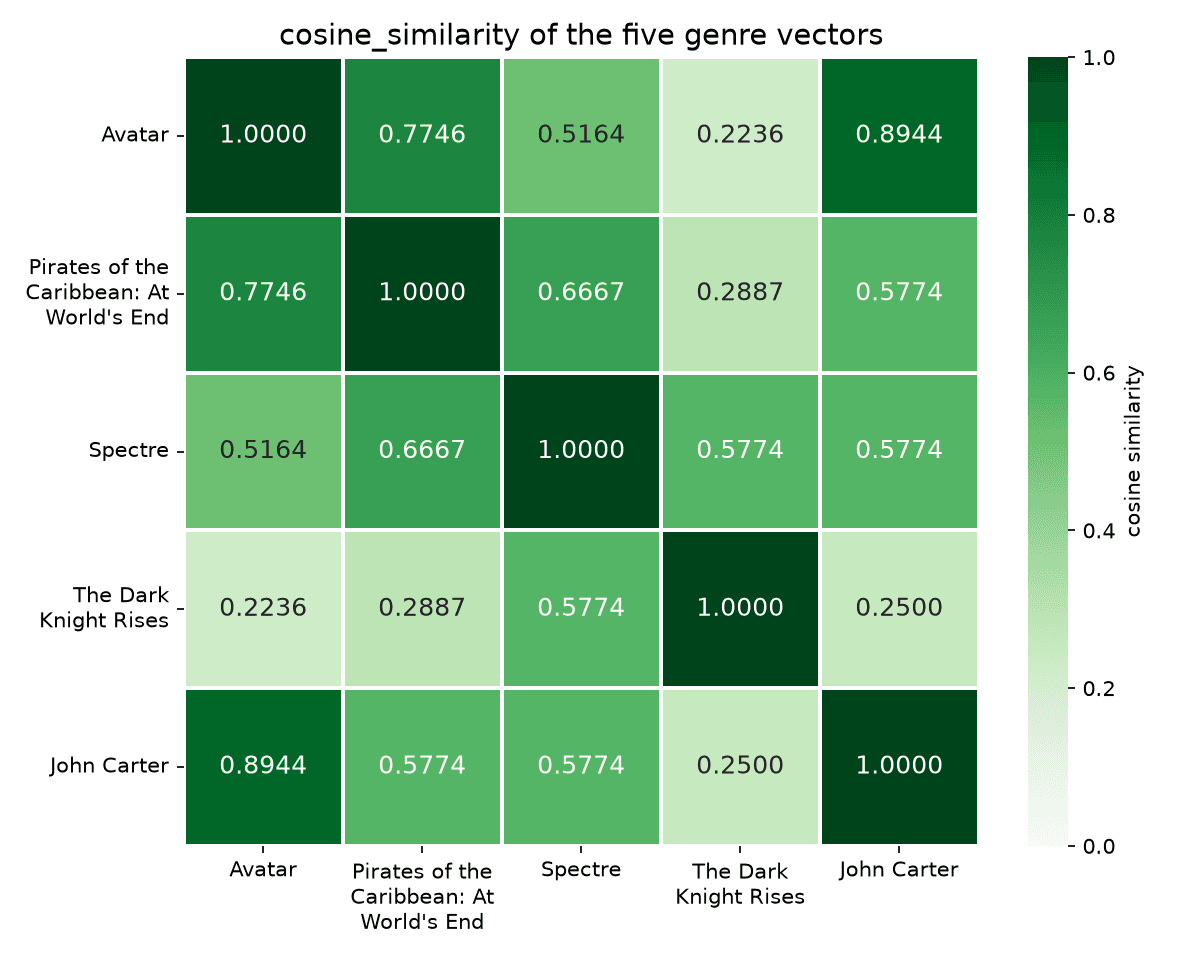
الجزء 2
المتجهات ومصفوفة التشابه
https://colab.research.google.com/github/
jeffprosise/Machine-Learning/blob/master/
Movie%20Recommendations.ipynbimport pandas as pd
url = ('https://raw.githubusercontent.com/'
'jeffprosise/Machine-Learning/'
'master/Data/movies.csv')
df = pd.read_csv(url)
df.shape(4803, 24): 4,803 أفلام، و24 عموداtitle وgenres وkeywords وcast وdirectordf = df[['title', 'genres', 'keywords', 'cast', 'director']]
df = df.fillna('') # Fill missing values with empty stringsdf['features'] = (df['title'] + ' ' + df['genres'] + ' ' +
df['keywords'] + ' ' + df['cast'] + ' ' +
df['director'])The Dark Knight Rises الكلمات dark وknight وrises (وthe من كلمات التوقف)vectorizer = CountVectorizer(stop_words='english', min_df=20)
word_matrix = vectorizer.fit_transform(df['features'])
word_matrix.shapeعمود features نفسه، مع stop_words='english'
| min_df | الكلمات المحتفظ بها |
|---|---|
| 1 | 17,286 |
| 5 | 3,852 |
| 20 (الدفتر) | 918 |
| 50 | 271 |
from sklearn.metrics.pairwise import cosine_similarity

sim = cosine_similarity(word_matrix)
sim.shape(4803, 4803): sim[i, j] هو قيمة جيب التمام بين الفيلمين i وjsim[i, j] يساوي sim[j, i]متجهات حقيقية من word_matrix
كل الأعداد تساوي 1 في المتجهين
| الكلمات من | Skyfall | Spectre | المشتركة |
|---|---|---|---|
| الأنواع | 3 | 3 | 2: action, adventure |
| الكلمات المفتاحية | 5 | 6 | 3: spy, secret, agent |
| أسماء طاقم التمثيل والإخراج | 7 | 6 | 6 |
| المجموع | 15 | 15 | 11 |
A = Skyfall، وB = Spectre
الجزء 3
get_recommendations سطرا بسطر
def get_recommendations(title, df, sim, count=10):
    # Get the row index of the specified title in the DataFrame
    index = df.index[df['title'].str.lower() == title.lower()]

    # Return an empty list if there is no entry for the specified title
    if (len(index) == 0):
        return []

    # Get the corresponding row in the similarity matrix
similarities = list(enumerate(sim[index[0]]))'skyfall' تعمل أيضا[] بدلا من خطأenumerate كل قيمة (score) برقم فيلمها، وفي Skyfall: (0, 0.1732), (1, 0.1333), (2, 0.7333), ... recommendations = sorted(similarities, key=lambda x: x[1], reverse=True)
top_recs = recommendations[1:count + 1]
titles = []
for i in range(len(top_recs)):
title = df.iloc[top_recs[i][0]]['title']
titles.append(title)
return titlesget_recommendations('Skyfall', df, sim)
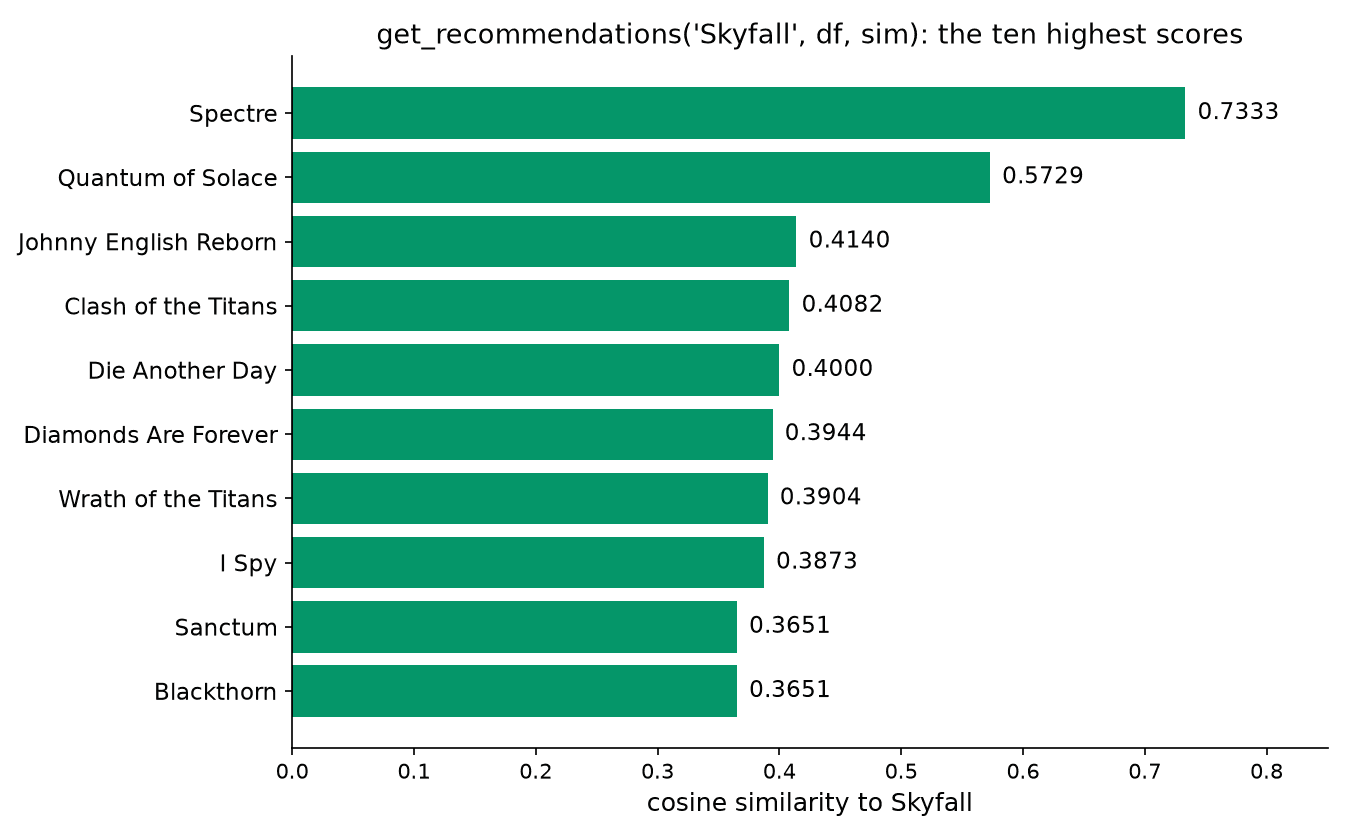
A = Mulan (10 كلمات)، وB = Shrek (15 كلمة)
min_df=20، لذا كل قيمة في صفها 0Batman، والدالة تستخدم دائما الأول[1:] الفيلم الخطأأحد المتجهات الفارغة الـ9
["Pirates of the Caribbean: At World's End", 'Spectre', 'The Dark Knight Rises']الجزء 4
مرحلة المشروع هذا الأسبوع
مشروع فريقك
قبل التمارين
Data/movies.csv في Colab، حيث لا يوجد المجلدfillna('')، فيعطل النص المفقود CountVectorizermin_dfالجزء 5
نحو 30 دقيقة، والإجابات تلي كل مهمة
نحو 10 دقائق
Adventure Action Thriller Crimeالإجابات
[1 1 1 0 0 0 0 1]، و‖A‖ = √4 = 2| الفيلم B | A · B | cos(A, B) |
|---|---|---|
| Spectre | 3 | 3 / (2 × 1.7321) = 0.8660 |
| The Dark Knight Rises | 3 | 3 / (2 × 2) = 0.7500 |
| Pirates of the Caribbean | 2 | 2 / (2 × 1.7321) = 0.5774 |
| John Carter | 2 | 2 / (2 × 2) = 0.5000 |
| Avatar | 2 | 2 / (2 × 2.2361) = 0.4472 |
نحو 5 دقائق
space war space alien، وY = space alien robot، وZ هو X مكتوبا مرتينalien, robot, space, war واكتب X وY وZ متجهات أعدادالإجابات
[1, 0, 2, 1]، وY = [1, 1, 1, 0]، وZ = [2, 0, 4, 2]نحو 10 دقائق
sim = cosine_similarity(word_matrix)get_recommendations واجعلها تعيد أزواجا (title, score)، مع تقريب القيمة إلى 4 منازل عشرية'The Dark Knight Rises'word_matrix: الضرب النقطي ومجموعا المربعاتالإجابات
| الترتيب | الفيلم | القيمة |
|---|---|---|
| 1 | The Dark Knight | 0.7924 |
| 2 | Batman Begins | 0.7348 |
| 3 | Harsh Times | 0.4667 |
| 4 | The Killer Inside Me | 0.4648 |
| 5 | Amidst the Devil's Wings | 0.4619 |
نحو 5 دقائق
(4803, 3852): تبقى كلمات أكثر بكثيرCountVectorizer النص إلى متجهات أعداد، ويحدد stop_words وmin_df الكلمات التي تحسبcosine_similarity المصفوفة كاملة، وصف مرتب واحد منها هو قائمة توصياتMahmoud Abas|التوصيات المعتمدة على المحتوى